







Generative AI adoption and benefits are increasing every day. Organizations are also rapidly experimenting with Generative AI solutions to solve their business problems.
However, there are several ways to implement Generative AI development solutions. The three popular implementation approaches include prompt engineering, fine-tuning, and retrieval augmented generation.
Prompt engineering is the fastest way to leverage the benefits of AI. LLM fine-tuning is an ideal approach for specialized and more stable domains. And RAG is the most enterprise-friendly and flexible option to work with internal data sources.
But which approach could be the best for your business operations?
When it comes to incorporating AI solutions into businesses, a common question leaders often face is: How can we maximize the value of AI using our organization's own knowledge base and data? And which one could be the most suitable approach for that?
Well, if you are also looking for answers to these questions, this blog is for you. In this blog, we will compare the three approaches - RAG vs fine-tuning vs prompt engineering to provide you with clarity.
You will also see how prompt engineering vs RAG plays out in practice, where fine-tuning vs RAG makes sense, and how to combine all three.
Retrieval Augmented Generation (RAG)
RAG is an advanced AI model architecture that combines two AI techniques- retrieval system and generation. It provides highly accurate and contextually relevant answers to users’ queries. RAG is a system that combines the strengths of language models with your enterprise's internal knowledge. Instead of retraining the model, RAG finds relevant documents or snippets in real-time and uses them in the prompt.

The retrieval component first searches a large knowledge database for relevant information. This information is then passed on to a generative model like LLM to create a coherent and precise response.

The RAG architecture is particularly used in applications that require high accuracy and detailed information, such as customer support, research assistance, and technical documentation. RAG systems can be pointed at different knowledge bases or industries without retraining the model, which makes them easy to adapt.
How Does RAG Work?
A RAG system runs in four steps:
-
Indexing: documents are split into chunks, converted into embeddings, and stored in a vector database.
-
Retrieval: the user's question is embedded and matched against the index. Many systems add keyword search and a reranker to improve precision.
-
Augmentation: the best passages are added to the prompt along with the question.
-
Generation: the LLM answers using that context and can point back to the source passages.
Modern RAG goes beyond basic chunk-and-embed. Production systems commonly combine hybrid search (keyword plus vector), reranking, and metadata filters. Newer agentic RAG setups let the model decide when to retrieve, rewrite its own queries, and check whether the evidence is enough before it answers. Retrieval quality sets the ceiling on answer quality, so teams that never evaluate the retrieval step often blame the model for errors that started earlier.
Did you know?💡
In March 2025, Gartner predicted that agentic AI will autonomously resolve 80% of common customer service issues by 2029, cutting operational costs by 30%. Retrieval from company knowledge is what lets those systems answer with current, accurate information.
Pros of RAG
-
Uses your internal knowledge securely
-
Extracts real time data from external data sources
-
Easy to update
-
No retraining required
-
Transparent & auditable
-
Reduces hallucinations by grounding answers in retrieved sources
- Model-agnostic, so you can swap the LLM without rebuilding the knowledge layer
- Can respect user permissions when access controls are applied at retrieval
Cons of RAG
-
More complex to set up than prompting: chunking, embeddings, a vector store, and retrieval testing
-
Answer quality depends on retrieval quality (chunking, embeddings, ranking)
-
Adds latency and ongoing infrastructure cost
-
Can still produce wrong answers if the retrieved context is wrong or incomplete
Use Cases of RAG for Enterprises
RAG offers different use cases for enterprises. In Enterprise Knowledge Management, RAG can be used in internal chatbots that reference internal resources and the database. RAG in Customer Service support bots that fetch information from product manuals and ticket histories. It also supports voice assistants in answering billing, service, or warranty questions.
Also Read: How RAG Improves Large Language Models to Deliver Real Business Value
Fine Tuning
Fine-tuning represents a method for adapting a foundation model or pre trained language model to a target task. In this process, a pre-trained model is further refined to excel in a particular domain, moving beyond the limitations of generic models.
Fine-tuning is less common than many assume. Organizations often choose to fine tune large language models when they require distinct advantages such as improved model's ability, higher accuracy, and specialized performance for domain-specific applications.
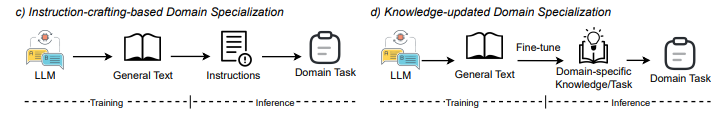
Fine-tuning involves training the LLM on a dataset particularly tailored to a specific task, which includes input and output pairs that demonstrate the target task and desired outcomes.
In the 2024 a study of 310 fine-tuned models, LoRA fine-tuned models beat their base models by 34 points on average and beat GPT-4 by 10 points on average across 31 tasks. The gains were largest on narrow, well-defined tasks such as classification.
For example, fine-tuning a model on legal documents enhances the model's ability to understand legal language, reasoning, and citations. This makes it highly relevant for legal AI applications. It can provide accurate results in well-defined domains and help achieve desired outcomes.

Pros of Finetuning LLMs
-
Highest control levels
-
Versatile as finetuning can be applied to varied models and tasks.
-
Tailored to specific domains
-
High Accuracy
Cons of Finetuning LLMs
-
Can be expensive
-
Time consuming
-
Less Flexible
-
Technical Expertise Needed
-
Data Dependency
- Does not reliably teach new facts, so knowledge goes stale until you retrain
- Risk of overfitting and of losing general abilities if the dataset is narrow
How does Fine-Tuning Work?
Fine-tuning involves adjusting the internal parameters of large language models using custom datasets. It works in the following process steps:

Data collection involves gathering examples relevant to the tasks, like customer support chats. Dataset preparation consists in formatting the data into input and output pairs. Model training uses machine learning tools to update the LLM's parameters to make it more accurate for the specific tasks. The deployment phase uses the fine-tuned models in the product through an API or server.
Full Fine-Tuning vs LoRA and PEFT
Most teams no longer update every weight in the model. Parameter-efficient fine-tuning (PEFT) methods such as LoRA and QLoRA train small adapter layers while the base model stays frozen. This cuts memory and compute sharply and lets one base model serve several tuned variants.
Data quality matters more than volume. A few hundred to a few thousand carefully curated examples often beat a large, noisy dataset. Fine-tuning works best for teaching behavior (format, tone, domain vocabulary, classification), not for loading facts. Facts change, and they are better handled with RAG.
Use Cases of Fine-Tuning for Enterprises
Fine-tuned LLM models can benefit businesses in many ways. Foe example, in the legal & compliance industry, fine-tuned LLM can be used for contract clause identification and risk scoring.
In the Healthcare industry, fine-tuned LLMs can be deployed as diagnostic assistants fine-tuned on clinical documentation. They can also perform patient data abstraction. In FinTech, LLM fine-tuning can be applied for fraud detection models trained on historical case data.
Prompt Engineering
Prompting is one of the easiest ways to interact with large language models. It is just similar to chatting with a friend. In prompt engineering, you provide LLMs with specific prompts about the type of information needed and its format. Prompt engineering is used to influence the model's behavior and guide the output toward specific goals.
By crafting optimal prompts, you can maximize the effectiveness of the model’s output and achieve the best results. This approach is valued for its cost efficiency compared to other methods.

Pros of Prompt Engineering
-
Easy to deploy
-
Works well with the general-purpose AI models like Gemini and Claude
-
Good for low-risk use cases
Cons of Prompt Engineering
-
Not connected to your internal data
-
Inconsistent as complexity grows
For example, whenever you use an LLM, say Gemini or ChatGPT. You chat like- "Write a fitness retail product description." This is considered a basic prompt. A very generic one with no trained instances. With prompt engineering, you give the model the context and constraints it needs to give a useful answer. For instance,
Engineered prompt: Write a 100-word product description for the fitness audience, highlighting the smart watch's key traits. Highlight its waterproof design, heart rate monitor, and activity tracking in a persuasive and friendly tone.
This prompt will provide a specific outcome because it states the audience, length, features, and tone.
How Prompt Engineering Works?
AI Prompt engineering doesn’t change the large language models. In fact, it works with the model’s existing knowledge, tests it with different prompts until it achieves the best outcomes. The goal is to develop optimal prompts through iteration and testing, ensuring the most effective and efficient results from the model. The technique involves the following:

Common Prompt Engineering Techniques
A handful of patterns cover most real-world prompting:
-
Zero-shot prompting: ask directly, with clear instructions and no examples.
-
Few-shot prompting: include two to five worked examples so the model copies the pattern.
-
Chain-of-thought prompting: ask the model to reason step by step before it answers.
-
Role and system prompts: set the persona, rules, and boundaries once for the whole conversation.
-
Structured output: request JSON or a fixed template so the result can feed other systems.
From Prompt Engineering to Context Engineering
Prompt engineering is now one piece of a wider practice called context engineering. Instead of polishing a single instruction, teams design everything the model sees at each step: system instructions, retrieved documents, tool definitions, memory, and conversation history. That is why prompt engineering and RAG are less like rivals and more like layers of the same system. It is also why rewording a prompt stops helping once an application grows past a simple chat.
Use Cases of Prompt Engineering for Enterprises
Prompt engineering can be used in a number of ways in varied industries. In Marketing Automation, Prompt engineering can be beneficial in generating blog headlines, ad copy, or product descriptions. It can also help create email campaigns using tone-specific prompts or even draft social media calendars with custom brand guidelines.
In Customer Support, Prompt Engineering can be used in answering FAQs using model knowledge without internal data integration. Now that we already have an understanding of all the approaches, let us find out how these are different in our next section.
RAG vs Fine-tuning vs Prompt Engineering: Key Differences
Each approach differs in how it influences model outputs and helps achieve desired outcomes, depending on the specific project goals and requirements. Take a glance at quick differences between RAG vs Fine tuning vs Prompt engineering.
|
Parameters |
RAG |
Fine Tuning |
Prompt Engineering |
|---|---|---|---|
|
Implementation Complexity |
Medium |
Complex |
Easy |
|
Quality of Model’s Output |
High Quality Outcome |
High Quality |
Variable based on the prompt |
|
Cost |
Medium |
High |
Low |
|
Data Requirements |
Medium |
High |
None |
|
Accuracy |
High |
High |
Variable |
|
Flexibility to Change |
High |
Low |
High |
|
Technical Expertise Required |
High for production |
Very High |
Low |
|
Maintenance |
Medium |
High |
Low |
We will now explore the differences between these approaches in a detailed comparison.
Implementation Complexity
RAG has moderate implementation complexity. This model requires architectural and coding skills to implement the retrieval mechanisms with generative models. Fine-tuning has a higher complexity. This is because it involves retraining models on specialized datasets and adjusting model parameters.
Prompt engineering has low implementation complexity. This is because it just involves refining input prompts rather than altering the model itself.
Output Quality of the Large Language Models
RAG provides high-quality outcomes of the LLMs. It enhances the model's output with contextually relevant retrieved information and provides up-to-date data from external data sources, improving both relevance and accuracy.
Fine-tuning offers high-quality outcomes as these are tailored to specific datasets. This ensures the model's output is more relevant and accurate for the intended use case. The outcome of prompt engineering is highly variable. This is because it is dependent on the skill in creating prompts, which directly influences the model's output in terms of relevance and accuracy.
Skills Level Required to Use the LLM
RAG requires a high skill level in production, as it involves a basic understanding of both machine learning and information retrieval systems. Fine-tuning requires a high skill level due to its reliance on knowledge of machine learning principles and model architectures. Prompt engineering needs a low skill level as a basic understanding of how to construct prompts can do the needful.
Cost Analysis of RAG vs Finetuning vs Prompt Engineering
The choice between RAG, fine-tuning, and prompt engineering also depends on budgetary constraints.
RAG can be resource-intensive and involves setting up and maintaining an external database for retrieval. So, the costs involved are moderate to high. In terms of cost efficiency, RAG offers a balance between performance and resource expenditure, but may not be as cost-efficient as prompt engineering. RAG also adds recurring costs for embeddings, vector storage, and the extra tokens that retrieved passages add to every request.
Fine-tuning needs additional data and significant computational resources for training. or example, parameter-efficient methods such as QLoRA can now fine-tune a 7B parameter model on a single GPU for roughly $1 to $15 in rented compute per training run. The larger costs sit around the run: curating and labeling data, evaluating results, and retraining whenever the data or base model changes. Full fine-tuning of the same model needs far more GPU memory and costs considerably more.. So, the costs involved in fine-tuning are higher. Fine-tuning is generally less cost-efficient compared to both RAG and prompt engineering due to its higher resource requirements.
Prompt engineering requires the least resources, as it uses the model as-is. So the costs involved in prompt engineering are less. Prompt engineering is the most cost-efficient approach among the three, achieving results with minimal resource expenditure.
Data Requirements
RAG has medium data requirements. This is because it needs access to relevant information sources or external databases to retrieve data. The data requirements in fine-tuning are high. This is because it requires a relevant and large training data for effective fine-tuning. Prompt engineering has no data requirements. It uses pre-trained language models without any additional data.
Also Read : Enhancing AI Interaction: A Guide to Prompt Engineering
Accuracy and Hallucination Risk
RAG delivers better quality results by using relevant context directly from organized information sources. It significantly reduces mistakes, known as AI hallucinations.
Fine-tuning offers highly accurate results, often similar in quality to RAG. This method updates the model's settings based on specific data. This allows it to give more relevant responses.
In a Microsoft Research agriculture case study, fine-tuning improved accuracy by more than 6 percentage points and RAG added another 5 percentage points on top, which shows the two techniques can stack.
For knowledge-heavy tasks, research presented at EMNLP 2024 found that RAG consistently beat unsupervised fine-tuning at getting new facts into a model.
RAG does not remove hallucinations, though. A 2024 Stanford study of commercial legal research tools built on RAG found they still hallucinated between 17% and 33% of the time. For high-stakes work, test retrieval quality, check citations, and keep a human in the loop.
Prompt engineering focuses on providing ample context with a few examples to help the model understand your specific situation. While the results may look good on their own, this method usually produces the least accurate responses compared to other approaches.
Flexibility to Change
RAG offers great flexibility for making changes to the architecture. You can change the embedding model, vector database store, and LLM independently with minimal impact on the other components.
Fine-tuning a model is less flexible. If there are changes in data or inputs, the model needs another fine-tuning cycle, which can be complicated and time-consuming. Also, it takes considerable effort to adapt a fine-tuned model for a different use case. The same model's weights and parameter-efficient fine-tuning might not work well in areas other than the one for which it was originally tuned.
Prompt Engineering is very flexible. You only need to change the prompt templates based on the updates in the FM and the specific use case.
Maintenance
RAG requires low to medium maintenance efforts. It mainly involves updating the external knowledge base or indexing new documents. So, there is no need to retrain the model. Fine-tuning needs high maintenance efforts. This is because it requires retraining when data changes, monitoring for model drift, and regular performance evaluation. Prompt engineering requires low maintenance efforts. It requires minimal upkeep, as it can adjust prompts as requirements evolve.
Security, Privacy, and Compliance
With RAG, your data stays in a store you control, and you can enforce document-level permissions at retrieval and log which sources produced each answer. That traceability helps in regulated industries. Fine-tuning bakes training data into the model weights, so sensitive records cannot be selectively removed later and may surface in outputs. Clean and review training data before you start. With prompt engineering, the main risk is pasting sensitive data into a third-party model without the right agreements in place.
Prompt Engineering vs RAG
Prompt engineering changes the instructions. RAG changes the information. If answers fail because of format, tone, or missed steps, fix the prompt. If they fail because the model lacks your data, or your data changes, add RAG.
-
Pasting reference text into a prompt works while the data is small and stable.
-
RAG takes over when the data is large, changes often, or needs citations.
-
Prompting is the better place to start because it is cheap to test and shows whether you need more.
Longer context windows help, but they do not make RAG obsolete. You pay for every token on every request, latency rises, and models can miss details placed in the middle of long inputs, as the "Lost in the Middle" research showed.
Fine-Tuning vs RAG
The simplest way to separate them: fine-tuning teaches the model how to behave, and RAG gives it what to know.
-
Choose RAG when knowledge changes often, answers need citations, or you need to update content without retraining.
-
Choose fine-tuning when you need consistent output format, tone, or classification across a high volume of similar requests.
-
Combine them when you need both: a tuned model that follows your format, fed by retrieved facts.
RAG, Fine-Tuning or Prompt Engineering: What Should Your Enterprise Choose?
After analyzing it all the discussion narrows down to only one question. Which one should your enterprise choose?
Well, it truly depends on your unique business requirements and the desired outcomes you want to achieve. Some organizations choose to use both RAG and other techniques like fine-tuning or prompt engineering together, as this hybrid approach can deliver more accurate, current, and reliable results. The choice of approach should always align with the specific goals and desired outcomes of your project. To help you refine the choice, below are some scenarios where choosing one could be ideal.
|
LLM Approach |
Ideal for |
When to Use |
|
Prompt engineering |
Simple tasks and limited resources |
|
|
Fine-tuning |
High accuracy and customization |
|
|
RAG |
Fact-based answers over private or changing data |
|
Fine-Tuning vs RAG vs Prompt Engineering: A Simple Decision Framework
Work through these questions in order:
-
Is the problem the format, tone, or steps of the answer? Start with prompt engineering.
-
Does the answer depend on private, changing, or citable information? Add RAG.
-
Do you need consistent behavior across a high volume of similar tasks, and do you have hundreds or thousands of quality examples? Consider fine-tuning.
-
Does your data change weekly or faster? Favor RAG over fine-tuning.
-
Still falling short? Combine approaches.
In practice the order is prompt first, RAG second, fine-tuning last. Each step costs more and commits you further, so move on only when the previous one has hit its limit.
Can You Combine RAG, Fine-Tuning, and Prompt Engineering?
Yes, and most mature systems do. The three work at different layers: prompts set instructions and guardrails, RAG supplies current facts, and fine-tuning shapes behavior. A support assistant might use a small fine-tuned model for ticket routing and brand voice, RAG over product manuals for answers, and a system prompt for escalation rules.
There are also hybrid techniques. RAFT (Retrieval Augmented Fine-Tuning) trains a model to use retrieved documents well, ignoring irrelevant ones and citing the right passages. And as the Microsoft agriculture study above showed, fine-tuning and RAG gains can add up.
Which Approach Fits Which Industry?
| Industry | Prompt engineering | RAG | Fine-tuning |
| Healthcare | Patient-facing FAQ chatbots and summaries | Searching current clinical guidelines and research | Diagnostic assistants and data abstraction trained on clinical notes |
| Financial services | Report summaries and email drafts | Real-time policy, market, and regulatory lookups | Fraud detection and transaction classification |
| Legal | First drafts of routine documents | Case law and clause retrieval with citations | Contract clause identification and risk scoring |
| Customer support | FAQ answers and reply drafts | Answers grounded in manuals and ticket history | Brand voice and ticket routing at high volume |
| Marketing | Headlines, ad copy, and campaign drafts | Product and location data pulled into copy | Consistent brand style across large content volumes |
Common Mistakes to Avoid
-
Fine-tuning to add facts. It is expensive, goes stale, and RAG does the job better.
-
Stuffing everything into the prompt. Costs and latency climb, and accuracy can drop as inputs get long.
-
Skipping retrieval evaluation. Bad chunks produce bad answers no matter how good the model is.
-
Starting without a test set. Build 50 to 100 real questions with expected answers first, so you can measure whether each change helps.
-
Treating the choice as permanent. Models, data, and needs change, so revisit the mix regularly.
Bottom Line
Choosing between prompt engineering, retrieval-augmented generation (RAG), and fine-tuning depends on your needs. Prompt engineering is a cost-effective and flexible way to improve how a model performs by refining prompts. RAG combines retrieval methods with generative models to provide rich and context-aware responses. Fine-tuning improves accuracy by retraining the model on specific datasets for particular tasks.
If you are starting today, begin with prompt engineering to prove the use case, add RAG when you need private or current knowledge, and fine-tune only when you have stable, high-volume tasks that need consistent behavior. Measure each step against a test set before you move to the next.
By understanding the strengths and weaknesses of each method, you can make better choices to use AI models effectively in your projects. If you are still unsure which approach is right for you, we are here to make things easier. Our AI strategy and consulting experts can help you select one. Get in touch today.
Frequently Asked Questions
Have a question in mind? We are here to answer. If you don’t see your question here, drop us a line at our contact page.
What is the difference between fine-tuning and prompt engineering?

Fine-tuning changes the model's internal weights by training it on new data. While prompt engineering changes only the instructions or input format. No model training is involved.
Is RAG a Prompt Engineering?
No. RAG (Retrieval-Augmented Generation) uses an external knowledge source to provide the model with fresh and relevant information before generating answers. Prompt engineering is just about designing better input prompts to get the desired outcomes.
Is RAG or fine-tuning better?
It truly depends on the unique business requirements. RAG is better if your data changes often. So, you can update the knowledge base without retraining. Fine-tuning is better for very specialized & stable tasks where the model must "learn" new patterns deeply.
What is the difference between RAG and few-shot prompting?
Few-shot prompting shows examples directly in the prompt to guide the model. RAG retrieves relevant information or facts from an external source automatically, without manually entering them into the prompt.
What is the difference between prompt engineering and fine-tuning vs RAG?
Prompt engineering, RAG, and fine-tuning are three distinct techniques for improving Large Language Model performance. Each one has its own approach, strengths, and resource requirements.
Prompt engineering means creating effective prompts that help guide the response of a language model. RAG improves answers by using information from outside sources. Fine-tuning means retraining the language model on a specific dataset so it can better focus its knowledge and behavior.
What is the difference between RAG architecture and fine-tuning?
RAG architecture keeps the base model as is but adds a retrieval system that feeds it relevant context. Fine-tuning, on the other hand, changes the model itself by training it on new datasets.